

How to Evaluate Recommendation Systems: Precision@K, Recall@K, NDCG and Business KPIs

Two recommendation models enter an offline benchmark. The hybrid model reports higher NDCG@10 than collaborative filtering, so the team declares it the winner. Later, they discover that the hybrid model was evaluated against 100 sampled negatives while collaborative filtering ranked the full catalog. One used a random split that leaked future interactions. The other used a temporal split. Their candidate counts differed, new items were removed from only one test set, and the business surface displays six not ten recommendations.
The scores were precise. The comparison was invalid.
Evaluation is not the final calculation after training. It is an experimental design that defines the decision, observation opportunity, data timeline, eligible corpus, candidate budget, labels, aggregation unit, model stage, and product outcome. Precision@K, Recall@K, and NDCG answer useful but different questions within that design. None proves that users received more value or that the business improved.
This guide provides a production protocol for comparing collaborative filtering, content-based recommendation, matrix factorization, hybrid systems, and ranking models fairly. It separates candidate generation from ranking, calculates the core metrics with worked examples, addresses leakage and exposure bias, adds diversity and operational measures, and turns the offline shortlist into a controlled online experiment.
Practical verdict: use Recall@K to test whether retrieval preserves relevant items, Precision@K to test how concentrated a returned list is with known positives, and NDCG@K when order and graded relevance matter. Calculate them on the same temporal split, eligible corpus, cutoff, ground-truth definition, and aggregation unit. Add coverage, diversity, novelty, latency, and safety guardrails. Choose the production winner through a powered online experiment tied to a business outcome not through one offline metric.
The Direct Answer: How Should a Recommendation System Be Evaluated?
Evaluate a recommendation system in five layers:
Data and protocol validity: correct timeline, labels, eligible items, candidate sets, and exposure assumptions.
Candidate-generation quality: Recall@K, hit rate, coverage, full-catalog retrieval, and retrieval latency.
Ranking quality: Precision@K, Recall@K, NDCG@K, MRR, calibration, and rank stability on a fixed candidate pool.
Final-slate and operational quality: diversity, novelty, duplication, safety, fairness, freshness, latency, availability, and cost.
Causal product impact: an online experiment measuring qualified user outcomes and business KPIs with guardrails.
Each layer answers a different failure question:
Layer | Question |
protocol | are we measuring a realistic, unbiased-enough future decision? |
candidates | did the system retrieve items worth ranking? |
ranker | did it put the stronger candidates earlier? |
slate | did policy and list construction create a useful final experience? |
online | did changing the recommendations cause the desired outcome? |
The established evaluation literature emphasizes choosing the user task and properties before selecting metrics. Herlocker and colleagues reviewed why recommender evaluations become incomparable when tasks and methods differ (ACM). Shani and Gunawardana distinguish offline experiments, user studies, and online experiments while treating accuracy, robustness, scalability, and other properties as application-dependent (Springer).
Start With an Evaluation Contract
An evaluation contract prevents models from winning through protocol differences.
decision: next eligible item for the home recommendation shelf
principal: authenticated user
prediction_time: request timestamp
catalog: items active and eligible at prediction_time
ground_truth: qualified interactions during the next 7 days
split: global temporal train / validation / test
candidate_evaluation: full eligible corpus
ranking_evaluation: fixed 500-item candidate pool
cutoffs: [5, 10, 20]
aggregation: macro-average by user, plus request-weighted diagnostic
primary_offline: NDCG@10
candidate_gate: Recall@500
guardrails: coverage, diversity, cold-item recall, p95 latency
online_primary: qualified conversion per eligible user
online_guardrails: returns, hides, latency, supplier concentration
Every report should make these choices visible:
recommendation task and surface;
unit of prediction;
data and catalog cutoff;
train, validation, and test windows;
user and item inclusion rules;
positive and graded-label definitions;
candidate construction and negative policy;
already-seen-item policy;
cutoff values;
per-user, per-request, or global aggregation;
baseline implementations and tuning budgets;
confidence intervals and comparison method;
operational test environment; and
online hypothesis and guardrails.
If one of these changes, the metric is a different experiment.
The Evaluation Stack: Do Not Collapse It Into One Score
Candidate-generation evaluation
Candidate generators search a large corpus. Their main job is high recall under latency and cost constraints. Compare collaborative filtering, content-based retrieval, matrix factorization, and two-tower retrieval here if each acts as a candidate source.
Measure:
Recall@K and Hit Rate@K;
catalog, category, supplier, and cold-item coverage;
full-corpus or exact-search quality;
ANN recall when approximate vector search is used;
candidates per request and empty-result rate;
p50/p95/p99 retrieval latency;
source freshness and index age; and
compute, memory, and cost.
Precision at a retrieval depth of 1,000 may be less important than recall because the downstream ranker can reject weak candidates. Candidate recall is the ceiling on downstream performance.
Ranking evaluation
Ranking compares items within a candidate pool. Hold that pool fixed when comparing ranking models. Measure:
NDCG@K for position-aware graded relevance;
Precision@K and Recall@K;
MRR when the first strong result dominates;
MAP for multiple binary-relevant items;
calibration when scores are interpreted as probabilities;
rank correlation and top-KK overlap; and
scoring latency and feature availability.
Slate evaluation
The final slate can differ from the model order after deduplication, diversity, quotas, business rules, sponsorship, and safety constraints. Recalculate accuracy metrics on the displayed order, then add slate measures.
Online evaluation
Historical data cannot fully model how a new policy changes exposure and behavior. A randomized experiment estimates causal impact under real users, UI, latency, inventory, and feedback loops.
Precision@K: How Much of the Top K Is Relevant?
For user or request uu, let RuKRuK be the top KK recommended items and GuGu the known relevant set:

If five recommendations contain two known relevant items:

What Precision@K tells you
It measures the concentration of known positives near the top. It is useful when:
visible slots are scarce;
irrelevant results create a clear cost;
the ground truth contains reliable positives and negatives; or
a user sees exactly or approximately KK items.
What it does not tell you
Precision@K ignores relevant items that were missed outside the top KK. It also treats unobserved items as non-relevant under common offline protocols, even though the user may never have encountered them.
Precision can favor conservative systems that repeat obvious head items. Pair it with Recall@K, coverage, novelty, and business outcomes.
Edge cases
If the system returns fewer than KK items, decide whether the denominator remains KK or becomes returned count. For production accountability, retaining KK penalizes incomplete lists.
If relevance is graded, binary Precision@K discards those grades. Use NDCG or a thresholded definition.
If a user has no future positives, Precision@K becomes zero under one convention and undefined under another. Report the convention.
Recall@K: How Much Known Relevance Did We Recover?

If the user has four known relevant items in the evaluation window and two appear in the top five:

What Recall@K tells you
Recall measures how much of the known relevant set the recommendation list recovered. It is central for candidate generation because a ranker cannot recover an item excluded upstream.
Interpretation depends on the ground-truth window
A 24-hour test window and a 30-day test window create different ∣Gu∣∣Gu∣. Longer windows may increase positives but mix changing intent. Compare models only under the same horizon.
Recall@K versus Hit Rate@K
Hit Rate@K is 1 if at least one relevant item appears and 0 otherwise:

If each evaluation case has exactly one held-out positive, Recall@K and Hit Rate@K are numerically identical. With multiple positives, they are not. State the protocol so readers know what the metric means.
Candidate recall versus final recall
Measure both:
candidate_recall@500: did retrieval find the relevant item?
final_recall@10: did ranking preserve it in visible positions?
The difference diagnoses ranking loss.
NDCG@K: Are the Strongest Items Near the Top?
Precision and Recall ignore order within the first KK. NDCG Normalized Discounted Cumulative Gain—rewards placing more relevant items earlier and supports graded relevance. Järvelin and Kekäläinen introduced the gain-based evaluation framework in information retrieval (ACM).
For relevance grade relkrelk at position kk:

Sort the same relevance grades ideally to calculate IDCG@KIDCG@K:

NDCG is normally between 0 and 1 when gains are nonnegative and normalization is defined.
Worked binary example
Suppose the relevant set is {A, C, F, H} and the top five are:
1. A  relevant
2. B  not observed as relevant
3. C  relevant
4. D  not observed as relevant
5. E  not observed as relevant
With binary relevance:

The ideal top five would place all four known positives first:

Therefore:
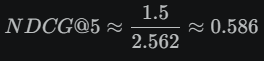
The same list has Precision@5 of 0.40 and Recall@5 of 0.50. The metrics describe different aspects of the same result.
Graded relevance
Grades might map to outcomes:
Grade | Example |
0 | examined with no qualified action |
1 | qualified click or short engagement |
2 | save, long dwell, or meaningful progress |
3 | add to cart, application, or strong intent |
4 | purchase, completion, or successful resolution |
The exponential gain 2rel−12rel−1 makes higher grades much more valuable. That is a product decision. Test linear gain when grade differences should be less dramatic.
NDCG edge cases
When IDCG@K=0IDCG@K=0, define whether to skip the group or assign zero.
Ties require deterministic handling.
Different libraries may use different gain functions or averaging conventions.
NDCG@10 and NDCG@100 optimize different user experiences.
NDCG from a sampled candidate set is not comparable with full-catalog NDCG.
Metric Implementation Details That Change Results
Macro versus micro averaging
Macro averaging calculates a metric per user or request, then averages:

Each user receives equal weight.
Micro averaging aggregates hits and denominators first. Highly active users or requests with many positives can dominate.
Report macro by user for a user-centric primary view and request-weighted or event-weighted diagnostics when operational traffic matters. Do not switch averaging silently.
Users with no test positives
These users matter in production but cannot contribute to conventional recall. Report:
how many were excluded from relevance metrics;
fallback quality and coverage for them;
qualitative or judged relevance where available; and
business outcomes in the online experiment.
Seen-item filtering
If the product should not recommend consumed items, remove them from eligible candidates for every model. If repeat purchase or rewatch is valid, define a time window or product-specific rule.
Duplicate and variant treatment
Evaluating every size/color variant as a separate hit can inflate metrics and reward repetitive lists. Choose canonical item, parent, or variant-level relevance according to the surface.
Multiple actions on one item
Deduplicate ground truth by item unless repeated consumption is the task. For sequential recommendations, evaluate each decision time separately.
Relevance threshold
If ratings exist, decide whether 4–5 stars are positive, 3–5, or graded. If implicit feedback exists, define qualified engagement rather than treating every click equally.
Library consistency
Metric names do not guarantee identical implementations. Research has documented inconsistent definitions across recommender libraries (Quality Metrics in Recommender Systems). Maintain small hand-calculated fixtures for every metric and pin the implementation version.
Build a Temporal Evaluation That Matches Production
Global temporal split
Choose cutoffs:
training window ---- validation window ---- test window
                 T_val                T_test
Train using events available before TvalTval, tune on the next period, retrain according to the planned process, and test on a later untouched period. Catalog eligibility and features must also be reconstructed at each prediction time.
Why random splitting fails
Randomly distributing interactions can place a user’s later behavior, a future-popular item, or a future catalog state in training while testing an earlier decision. The model benefits from information unavailable in deployment.
The study A Critical Study on Data Leakage in Recommender System Offline Evaluation documents leakage problems in offline protocols. A 2025 RecSys study found that split choices can materially change results and model rankings; it recommends matching the split to the production task (ACM).
Simulate the inference state
At each test decision:
use only the history available before that time;
reconstruct the eligible catalog;
exclude unavailable or unauthorized items;
generate candidates with artifacts trained before the cutoff;
calculate point-in-time features;
score and construct the slate; and
compare with outcomes inside the defined future window.
Cold-start cohorts
Create explicit slices:
new user: no prior history;
short-history user: fewer than a chosen number of events;
established user;
new item: created after training cutoff;
tail item: low prior exposure or interaction;
head item;
changed metadata or category; and
new market or locale.
A global average can conceal that content-based methods win cold-item evaluation while collaborative methods win mature inventory.
Use the Full Eligible Corpus Whenever Feasible
Ranking one positive against 99 random negatives is not the same as searching a million-item catalog. Random negatives are often easy, and the sampled protocol can change model ordering.
The KDD paper On Sampled Metrics for Item Recommendation shows that sampled metrics can be inconsistent with exact metrics and may not preserve relative comparisons between recommenders.
Recommended hierarchy
evaluate against the full eligible corpus;
if vector search is used, compare ANN results with exact retrieval on a representative reference set;
use distributed or batched full-corpus evaluation for release gates;
use fixed samples only for rapid development diagnostics; and
label sampled metrics clearly, including sampler and seed.
If sampling is unavoidable
Hold constant:
number of negatives;
sampling distribution;
eligibility rules;
randomness seeds or repeated seeds;
treatment of popular and hard negatives; and
metric implementation.
Never compare a reported Recall@10 from one sampled protocol with another Recall@10 as though the numbers were universal.
Exposure Bias: Missing Does Not Mean Irrelevant
Historical interactions are generated by previous recommendation, search, merchandising, and UI policies. An item cannot receive a click if it was never shown or examined.
Bias sources
previous model selection;
display position;
carousel or grid visibility;
image size and badges;
popularity and marketing;
inventory and eligibility;
notification delivery;
user self-selection; and
geography or language.
Naively treating every unobserved user-item pair as negative rewards the previous policy. Exposure bias can also propagate through feedback loops; Gupta et al. analyze correction using exposure probabilities for link recommendation.
Better evidence
log eligibility, retrieval, display, and examination separately;
use controlled randomization inside safe candidate sets;
collect editorial or expert judgments;
estimate propensity where assumptions are defensible;
clip high inverse-propensity weights;
evaluate on exploration traffic; and
maintain qualitative error review.
Counterfactual estimators depend on overlap: if the logging policy never exposed a region of the catalog, historical data cannot reliably estimate a new policy there without stronger assumptions or new exploration.
Compare Algorithm Families Fairly
Collaborative filtering, content-based recommendation, matrix factorization, hybrid systems, and ranking models do not necessarily occupy the same pipeline stage. A fair experiment begins by deciding what is being compared.
Experiment A: candidate-generator bake-off
Compare:
item- or user-based collaborative filtering;
content-based retrieval;
matrix factorization;
a hybrid candidate source; and
optionally a two-tower retriever.
Hold constant:
training/validation/test timeline;
eligible corpus;
user histories and event weights;
candidate count KK;
seen-item and variant filters;
ground truth;
hyperparameter budget;
full-corpus evaluation protocol; and
hardware/latency measurement conditions.
Primary metrics: Recall@K, Hit Rate@K, coverage, cold-start recall, latency, memory, freshness, and cost.
Do not include a powerful downstream ranker for only one candidate source. Either compare raw retrieval or feed each source into the same fixed ranker.
Experiment B: ranking-model bake-off
Freeze the candidate pool and compare:
heuristic weighted score;
pointwise boosted model;
LambdaMART or other LTR model;
hybrid ranking model; and
neural ranking model if justified.
Primary metrics: NDCG@K, Precision@K, Recall@K, calibration where applicable, final-slate metrics, inference latency, feature availability, and cost.
Experiment C: end-to-end policy comparison
Compare complete pipelines, such as:
collaborative candidates + baseline ranking;
content + collaborative blend + baseline ranking;
matrix factorization + LTR;
two-tower + CF + content + LambdaMART + reranking; and
current production policy.
This experiment answers which system should serve, but it does not isolate which component caused the difference. Pair it with component ablations.
Hybrid is a configuration, not one algorithm
Document exactly how sources are combined:
quota union;
normalized score blend;
reciprocal rank fusion;
feature-level learned ranking;
switching by cohort; or
separate cold-start policy.
“Hybrid” without a definition is not reproducible.
What to Expect From Each Approach
These are hypotheses to test, not guaranteed outcomes.
Approach | Likely strength | Likely weakness | Priority slices |
collaborative filtering | mature behavioral affinity and interpretable co-interest | cold start, sparsity, popularity bias | history density, item age, popularity |
content-based | new-item and semantic coverage | overspecialization and metadata dependence | metadata completeness, locale, new items |
matrix factorization | compact latent preference and strong mature baseline | ID cold start and limited context | head/tail, profile length, new IDs |
hybrid | broader coverage across failure modes | complexity, calibration, source dominance | source contribution, cold/warm cohorts |
ranking model | contextual ordering and cross-features | cannot recover missing candidates; biased labels | candidate source, surface, feature freshness |
Detailed implementation guides are available for collaborative filtering, content-based recommendation, two-tower retrieval, and learning-to-rank. The production recommendation architecture pillar shows how they fit into one platform.
Beyond Accuracy: Measure the Experience and Supply
Catalog coverage
What fraction of eligible items appears in at least one recommendation?

High coverage does not guarantee fair or useful exposure, but low coverage may reveal head-item concentration.
User coverage
What fraction of eligible requests receive at least KK valid recommendations? Break out new users, rare locales, restrictive entitlements, and short histories.
Intra-list diversity
Average pairwise distance among recommended items:

The distance representation determines meaning. Category distance, content-embedding distance, and supplier difference capture different forms of diversity.
Novelty
One popularity-based novelty measure is self-information:

Average it across the slate, but avoid rewarding obscure irrelevant items. Measure novelty jointly with relevance.
Serendipity
Serendipity combines relevance with unexpectedness relative to a baseline. It is difficult to infer purely offline because surprise is user-dependent. Use user studies, explicit feedback, and online behavior where possible.
Calibration
A calibrated slate matches a user’s preference distribution across attributes such as categories, genres, difficulty, or price bands. It is different from probability calibration.
Fairness and exposure
Measure position-discounted exposure, relevance conditional on group, pairwise accuracy, opportunity, and outcome across relevant consumer and provider groups. Consult legal and domain experts before defining protected or operational groups.
Negative outcomes
Track hides, blocks, returns, cancellations, complaints, rapid abandonment, and support contacts. A recommender can improve clicks by making recommendations more provocative or misleading.
Research has long argued for coverage and serendipity beyond predictive accuracy (Ge, Delgado, and Jannach). More recent work continues to study joint relevance and diversity metrics (Google Research).
Operational Metrics Are Release Gates
Dimension | Metrics |
latency | p50, p95, p99 end-to-end and per stage |
availability | success, partial success, timeout, fallback rate |
freshness | event-to-profile, catalog-to-index, model age |
scale | peak QPS, candidates scored, shard distribution |
resource | CPU/GPU, memory, network, storage, cache hit |
cost | per 1,000 requests, per million candidates, per model release |
data | missing features, schema violations, late events |
retrieval | empty results, ANN recall, candidate count |
policy | eligibility rejects, duplicate removal, quota actions |
reliability | degraded-mode quality and recovery time |
A 1% offline gain that doubles p99 latency or fails on one region may not be deployable. Add operational thresholds to the model scorecard before selection.
Map Business KPIs to the Recommendation Surface
The business KPI must follow the decision, not a generic engagement template.
Commerce and marketplaces
qualified click-through rate;
add-to-cart and purchase conversion;
revenue or contribution margin per eligible user/session;
average order value and attach rate;
return, cancellation, and complaint rate;
discovery and sales coverage of eligible inventory;
supplier exposure and concentration; and
repeat purchase or retention.
Media and content
qualified play/start;
completion and watch/read/listen time with quality guardrails;
session depth and return rate;
hides, skips, or “not interested”;
novelty, creator/catalog coverage, and repetition; and
subscription retention.
Jobs and talent
qualified application start and completion;
recruiter response, interview, and hire;
time to relevant opportunity;
candidate and employer coverage;
repeated or unsuitable job rate; and
fairness and opportunity measures.
Learning
enrollment, meaningful progress, and completion;
skill assessment improvement;
time to proficiency;
abandonment or mismatch;
provider and topic coverage; and
learner retention.
B2B recommendations
qualified lead or next-best-action completion;
acceptance and resolution rate;
sales-cycle time;
contract-compliant adoption;
override rate and operator trust; and
operational savings.
The review Measuring the Business Value of Recommender Systems discusses the difficulty of translating algorithmic improvements and offline results into business value. Treat business impact as an empirical question.
Design the Online Experiment Before Choosing the Offline Winner
Write the hypothesis
Replacing the current candidate and ranking policy with the hybrid policy will increase qualified purchase conversion per eligible user by at least the minimum detectable effect, without increasing returns, p95 latency, supplier concentration, or safety violations beyond approved guardrails.
Choose the randomization unit
user/account: best for persistent personalization and retention;
session: useful for bounded anonymous journeys;
request: fast but risks inconsistent user experience;
marketplace, region, or store: required when interference is high;
switchback/time block: useful when capacity or shared supply makes simultaneous assignment difficult.
The unit used for statistical analysis must reflect assignment and correlation. Treating thousands of requests from one user as independent inflates confidence.
Define metrics before launch
Specify:
one primary KPI;
a small set of secondary explanatory metrics;
hard guardrails;
denominator and eligibility;
attribution window;
novelty/ramp period;
minimum duration;
sample-size and power method;
multiple-testing policy; and
stopping and rollback rules.
Instrument the funnel
eligible users
  -> recommendation request
  -> successful response
  -> item rendered
  -> item examined
  -> qualified action
  -> downstream business outcome
  -> negative or delayed outcome
An apparent conversion lift can come from a change in request frequency or response success. Use stable denominators such as per assigned eligible user where appropriate.
Prelaunch checks
sample-ratio mismatch;
treatment assignment consistency;
model and policy bundle routing;
event completeness and deduplication;
A/A test behavior;
latency and fallback parity;
novelty effects; and
cross-treatment contamination.
Analyze heterogeneity carefully
Predeclare important cohorts: new versus established users, new versus mature items, locale, surface, device, category, and supplier. Post-hoc slicing creates false discoveries if every subgroup is treated as confirmatory.
Netflix’s recommender-system paper describes using both offline experimentation and A/B testing tied to medium-term engagement and retention (ACM).
Statistical Confidence and Practical Significance
Use paired analysis offline
When two models score the same users or requests, compare per-unit metric differences. Paired bootstrap resampling over users or request groups can produce confidence intervals without assuming every item-level observation is independent.
Choose the resampling unit correctly
If user histories create correlation, resample users. If organizations are assigned together, resample organizations. Item-level bootstrap usually understates uncertainty.
Report uncertainty, not only means
For each primary metric, provide:
estimate;
absolute and relative difference;
confidence interval;
number of users/requests and positives;
aggregation method; and
cohort consistency.
Practical significance
A statistically significant NDCG increase of 0.0002 may not justify new infrastructure. Define minimum material improvements in quality, business value, or cost before testing.
Multiple comparisons
Comparing five models, many metrics, and dozens of cohorts creates false winners. Designate one primary comparison, use validation for model selection, preserve an untouched test set, and control or clearly label exploratory analysis.
Repeated tuning on the test set
Once test results influence feature or hyperparameter decisions, the test set becomes validation. Create a new future holdout or rolling evaluation for final claims.
A Reproducible Experiment Comparing Five Approaches
This section provides a concrete protocol. The numeric results are illustrative, not industry benchmarks.
Business context
An online retailer displays ten products on a personalized home shelf. The catalog contains 1.8 million eligible parent products. A qualified positive is an add-to-cart, purchase, or explicit save within seven days. Purchases receive grade 3, saves/add-to-cart grade 2, and qualified product views grade 1.
Models
Item-based collaborative filtering: co-interaction neighbors aggregated from recent user history.
Content-based: weighted metadata plus text embeddings.
Matrix factorization: implicit-feedback user/item factors.
Hybrid retrieval: union of CF, content, matrix factorization, and contextual popularity with reciprocal rank fusion.
Ranking model: the hybrid candidate pool followed by LambdaMART and a fixed diversity policy.
The fifth model is an end-to-end pipeline, not a peer candidate generator. Therefore the team runs two comparisons.
Data protocol
16 weeks training;
2 weeks temporal validation;
2 weeks untouched temporal test;
catalog and inventory reconstructed at decision time;
already purchased non-repeat products removed;
parent-product deduplication;
same event weights and user-history cutoff;
full eligible corpus for candidate evaluation;
same maximum candidate count of 500;
macro-average by eligible test user;
metrics at 10 because the surface displays ten items; and
separate new-item and short-history cohorts.
Candidate-generator results
Model | Recall@500 | Hit Rate@500 | Catalog coverage | New-item Recall@500 | p95 retrieval | Interpretation |
item CF | 0.742 | 0.811 | 31% | 0.083 | 18 ms | strongest mature behavioral baseline |
content | 0.611 | 0.704 | 58% | 0.521 | 24 ms | strongest cold-item and coverage result |
matrix factorization | 0.768 | 0.826 | 27% | 0.041 | 14 ms | strong warm-user/item recall, concentrated exposure |
hybrid | 0.842 | 0.889 | 64% | 0.566 | 33 ms | best overall recall within latency gate |
These illustrative numbers support the hybrid candidate pool. They do not prove its final ordering is better.
Ranking results on the same hybrid pool
Ranker | Precision@10 | Recall@10 | NDCG@10 | Intra-list diversity | p95 ranking | Interpretation |
source-fusion baseline | 0.086 | 0.214 | 0.171 | 0.48 | 4 ms | inexpensive control |
pointwise boosted model | 0.094 | 0.232 | 0.188 | 0.44 | 9 ms | better relevance, lower diversity |
LambdaMART + fixed rerank | 0.101 | 0.247 | 0.204 | 0.51 | 14 ms | best offline top-ten balance |
The team validates differences with paired user-level bootstrap confidence intervals and checks item-age, history-length, category, and supplier cohorts.
Online experiment
Control uses the current production hybrid and source-fusion rank. Treatment uses the same retrieval sources plus LambdaMART and the approved reranker.
primary: qualified purchase conversion per assigned eligible user;
secondary: add-to-cart, saves, revenue per eligible user;
user guardrails: returns, hides, complaints, seven-day return rate;
system guardrails: p95/p99 latency, errors, fallbacks;
supply guardrails: catalog coverage and supplier concentration;
assignment: user-level;
duration: at least two complete weekly cycles after ramp, subject to the powered design; and
decision: ship only if the primary KPI improves materially and no guardrail crosses its threshold.
This is an actual experiment because model stages, offline protocol, and online decision criteria are explicit.
The Recommendation Evaluation Scorecard
Category | Primary measures | Required slices | Release question |
protocol | leakage checks, eligible corpus, label maturity | time, surface | does the test represent deployment? |
candidates | Recall@K, Hit Rate@K | cold/warm, head/tail, source | were useful items available? |
ranking | NDCG@K, Precision@K, Recall@K | user/item cohorts | were strong items ordered early? |
slate | diversity, novelty, duplication, coverage | category, supplier | is the final list useful and varied? |
bias | exposure opportunity, propensity sensitivity | position, layout, group | are conclusions driven by old exposure? |
operations | latency, availability, freshness, cost | region, fallback | can the system serve reliably? |
governance | authorization, safety, deletion, fairness | tenant and relevant groups | is deployment acceptable and auditable? |
online | primary business KPI and guardrails | predeclared cohorts | did the policy cause incremental value? |
Keep the scorecard versioned with the model release. A metric without its protocol is not a reusable artifact.
Common Evaluation Failures
Failure | Why it invalidates the result | Correction |
random split leaks future behavior | test no longer represents a future decision | global temporal split and point-in-time features |
different negative samples per model | difficulty changes with the model | full corpus or identical fixed samples |
only RMSE for top-N task | rating error does not measure list quality | Precision/Recall/NDCG at interface cutoffs |
ranking model gets a better candidate pool | retrieval and ranking effects are confounded | freeze candidates or call it end-to-end comparison |
all missing pairs are negative | old exposure policy becomes ground truth | exposure logging, exploration, judgments, correction |
active users dominate aggregation | metric represents activity, not users | macro-average by user plus weighted diagnostic |
variants count as independent hits | repetitive lists receive inflated credit | canonical parent evaluation and deduplication |
NDCG cutoffs do not match UI | metric optimizes invisible positions | use surface-specific KK and discount |
hybrid is undefined | result cannot be reproduced | document fusion, weights, quotas, and sources |
no cold-start slices | aggregate hides core failure mode | cohort evaluation by history and item age |
sampled NDCG called full-catalog NDCG | metric magnitude and ordering differ | label protocol and run full-corpus gate |
no statistical uncertainty | noise can appear as improvement | paired intervals and predeclared comparison |
test set used repeatedly | selection overfits the holdout | new future test or rolling evaluation |
offline winner ships directly | historical relevance is not causal impact | controlled online experiment |
clicks are the only online KPI | model can optimize curiosity or manipulation | qualified outcomes and negative guardrails |
mean latency only | tail failures are hidden | p50/p95/p99 and stage traces |
slate metrics calculated before reranking | displayed experience is not evaluated | score final displayed order |
experiment denominator changes | request frequency masquerades as conversion | stable eligible-user/session denominators |
Operationalizing Evaluation in MLOps
Validation pipeline
Every candidate release should automatically:
verify event, catalog, feature, and label schemas;
freeze temporal datasets and manifest hashes;
train or load baselines under equal budgets;
run full-catalog candidate evaluation;
evaluate ranking on fixed production-like pools;
construct and score final slates;
calculate cohort and beyond-accuracy metrics;
benchmark latency, memory, and cost;
run security and policy tests;
compare with release thresholds; and
publish a model/evaluation card.
Evaluation artifact
Store:
data and catalog cutoffs;
code, configuration, and dependency versions;
eligible-item logic;
labels and attribution windows;
sampled/full-corpus protocol;
metric definitions and fixtures;
per-user/request metric output where privacy permits;
aggregate and cohort results;
confidence intervals;
resource benchmarks;
known limitations; and
approval decision.
Continuous monitoring
Offline gates do not replace production monitoring. Track metric proxies, outcomes, feature drift, candidate source mix, rank distributions, coverage, diversity, latency, fallback, and delayed negatives. Re-run exact/full-catalog evaluation periodically and after retrieval/index changes.
Codersarts resources on CI/CD for machine learning and continuous training and automated retraining pipelines explain how to embed these gates into promotion workflows. For implementation, see the Codersarts MLOps service.
An Evaluation Plan You Can Copy
1. Decision and outcome
Surface:
Eligible population:
Number of visible slots:
Primary user decision:
Primary business outcome:
Outcome window:
Negative outcomes:
Hard policy constraints:

2. Data protocol
Training cutoff/window:
Validation cutoff/window:
Test cutoff/window:
Catalog snapshot logic:
Point-in-time feature method:
Ground-truth definition:
Seen/repeat item policy:
Canonical item/variant policy:
Cold-user/item definitions:

3. Candidate experiment
Models/sources:
Eligible corpus:
Full-corpus or sampling protocol:
Candidate count(s):
Primary retrieval metric:
Coverage and cold-start metrics:
Latency/memory/cost gates:

4. Ranking experiment
Frozen candidate pool:
Rankers:
Relevance grades/gains:
Cutoff(s):
Primary ranking metric:
Slate policy:
Diversity/novelty/coverage guardrails:
Inference-latency gate:

5. Statistical protocol
Aggregation unit:
Confidence method:
Primary comparison:
Multiple-testing policy:
Minimum material improvement:
Untouched test-set owner:

6. Online experiment
Hypothesis:
Assignment unit:
Control/treatment bundles:
Primary KPI:
Secondary diagnostics:
Guardrails:
Minimum detectable effect:
Planned sample and duration:
Ramp and rollback rules:

7. Decision record
Offline result:
Cohort limitations:
Operational result:
Online result:
Risk review:
Ship/iterate/stop decision:
Owner and date:
Frequently Asked Questions
Which metric is best for recommendation systems?
There is no universal best metric. Use Recall@K for retrieval coverage, Precision@K for top-list concentration, NDCG@K for position-aware graded relevance, and business KPIs from an online experiment for causal product impact. Add diversity, coverage, negative outcomes, latency, and policy guardrails.
What is a good Precision@K or NDCG@K score?
There is no universal threshold. Values depend on catalog size, number of positives, data split, candidate protocol, cutoff, metric implementation, and domain. Compare with strong baselines under the same protocol and require material online value.
Should we use Precision@K or Recall@K?
Use both when practical. Precision asks how many displayed items are relevant; Recall asks how much known relevance was recovered. Retrieval systems usually prioritize Recall@K, while small high-cost slates often care strongly about Precision@K.
When is NDCG better than Precision or Recall?
Use NDCG when order matters and especially when relevance is graded. It rewards placing high-value items earlier. Precision and Recall remain easier to interpret and useful alongside it.
Is Recall@K the same as Hit Rate@K?
Only when each evaluation case has exactly one relevant item. With multiple relevant items, Hit Rate measures whether at least one was found, while Recall measures the fraction found.
Can we compare metrics reported in different papers or tools?
Only when the datasets, splits, candidate corpus, negative sampling, filters, cutoff, ground truth, aggregation, and metric definitions match. Usually they do not match closely enough for direct numerical comparison.
Why does a popularity baseline matter?
Popularity is simple, strong for cold users, and exposes whether complex models merely reproduce head-item frequency. Use eligible, contextual, and time-aware popularity rather than a careless global count.
How should matrix factorization be compared with collaborative filtering?
Use the same implicit-event weighting, temporal data, eligible catalog, candidate count, seen-item policy, and full-corpus metrics. Tune both under comparable budgets and report cold-start, coverage, latency, and storage—not only aggregate accuracy.
How do we evaluate a hybrid recommendation system?
Define every source and fusion rule, measure source-specific recall and contribution, then evaluate the merged pool and final ranking. Compare the hybrid with its components through ablations and with the production policy in an online experiment.
How large should K be?
Use values matching the system stage and interface. Candidate generation may use hundreds or thousands. Final ranking uses visible positions such as 5, 10, or 20. Plot curves across several K values rather than selecting one after seeing results.
How do we evaluate new users and new items?
Create explicit temporal cohorts based on history length and item creation/exposure time. Include content or fallback policies in the comparison. Report coverage, quality, and business outcomes separately from established users/items.
Do offline metrics predict A/B-test results?
They are screening and diagnostic tools, not guarantees. Historical exposure, UI effects, latency, feedback loops, and changing behavior can break correlation. Use offline gates to select safe candidates and online experiments to estimate causal impact.
What is the minimum viable evaluation for a proof of concept?
A temporal split, eligible-catalog reconstruction, popularity baseline, at least one model baseline, full-corpus or clearly fixed sampling, Precision/Recall/NDCG at relevant K, cold-start and coverage slices, latency measurement, and a documented online hypothesis. Anything less is a demo, not a defensible comparison.
Make the Experiment Reproducible Before Making the Model Complex
Recommendation metrics are meaningful only inside their protocol. Precision@K measures the density of known relevance. Recall@K measures recovered known relevance. NDCG adds rank and graded gain. Coverage, diversity, novelty, fairness, latency, reliability, and cost reveal whether the list can serve the wider product. Online business KPIs determine whether changing the policy caused value.
The evaluation system should make it impossible for one approach to gain an invisible advantage through a different split, sampled corpus, candidate budget, filter, or metric implementation. It should also make each loss traceable: retrieval, ranking, reranking, policy, delivery, examination, or outcome.
Codersarts helps enterprise teams design recommendation benchmarks and production experiments across collaborative filtering, content-based models, matrix factorization, two-tower retrieval, hybrid systems, learning-to-rank, business KPI design, deployment, and monitoring. Explore our machine learning development services, machine learning deployment services, and MLOps services.
Need a defensible comparison rather than another offline leaderboard? Discuss your recommendation-system evaluation with Codersarts.
Primary References
Herlocker, J. L., Konstan, J. A., Terveen, L. G., and Riedl, J. T. “Evaluating Collaborative Filtering Recommender Systems.” ACM TOIS, 2004. ACM DOI.
Shani, G., and Gunawardana, A. “Evaluating Recommendation Systems.” In Recommender Systems Handbook, 2011. Springer DOI.
Järvelin, K., and Kekäläinen, J. “Cumulated Gain-based Evaluation of IR Techniques.” ACM TOIS, 2002. ACM DOI.
Krichene, W., and Rendle, S. “On Sampled Metrics for Item Recommendation.” KDD, 2020. Google Research.
Ji, Y., Sun, A., Zhang, J., and Li, C. “A Critical Study on Data Leakage in Recommender System Offline Evaluation.” ACM TOIS, 2023. ACM DOI.
Gusak, D., et al. “Time to Split: Exploring Data Splitting Strategies for Offline Evaluation of Sequential Recommenders.” RecSys, 2025. ACM DOI.
Gupta, S., Wang, H., Lipton, Z., and Wang, Y. “Correcting Exposure Bias for Link Recommendation.” ICML, 2021. PMLR.
Ge, M., Delgado, C. A., and Jannach, D. “Beyond Accuracy: Evaluating Recommender Systems by Coverage and Serendipity.” RecSys, 2010. ACM DOI.
Jannach, D., and Jugovac, M. “Measuring the Business Value of Recommender Systems.” ACM TMIS, 2019. ACM DOI.
Gomez-Uribe, C. A., and Hunt, N. “The Netflix Recommender System: Algorithms, Business Value, and Innovation.” ACM TMIS, 2015. ACM DOI.


Comments